OpenAI announces GPT-6 Astra: what the new flagship model release means
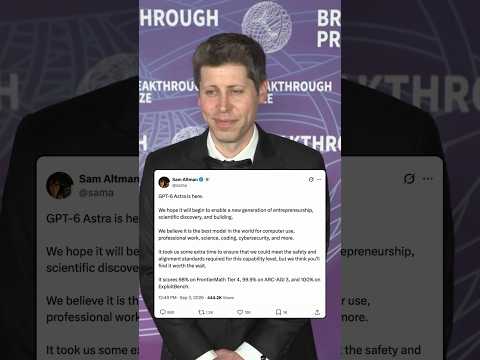 Photo: N43 and Hermes
technology
Sam Altman has announced GPT-6 Astra, the next flagship in OpenAI's model line. The name follows the company's recent convention of pairing a generation number with a variant label, and the announcement arrives on a cadence that has compressed from years to months. What the launch actually tells us, and what it cannot.
Video: Sam Altman just announced GPT-6 Astra - Yahoo Finance, ~800 views observed September 3, 2026. View counts change over time.
01What OpenAI announced with GPT-6 Astra
OpenAI's chief executive announced GPT-6 Astra as the company's newest flagship model, in a reveal covered by Yahoo Finance within a day of the news breaking. By the standards of previous generations, the announcement itself was the news: a name, a position in the product hierarchy, and an implicit promise that benchmarks and availability details would follow. That pattern of announcing first and publishing full evaluations later has become the industry norm, and it is worth holding in mind before drawing conclusions about capability jumps.
What is verifiable at announcement time is the lineage. GPT-6 is the successor to GPT-5, which itself succeeded GPT-4 in 2023 and GPT-3 in 2020, a cadence that has visibly accelerated. The "Astra" tag follows the naming style OpenAI has used to distinguish variants within a generation, most recently with GPT-5 Astra, signaling that this is the full-capability tier rather than a smaller or specialized derivative. OpenAI is a public benefit corporation headquartered in San Francisco whose GPT series of large language models has anchored its product line since 2020.
What is not verifiable yet is the substance. Announcement events historically disclose capability claims, safety testing summaries, and rollout timelines, with detailed technical reports following weeks to months later. Until independent evaluations appear, the strongest signal in any launch is the fact that it happened at all: OpenAI judged that a new flagship was ready to ship against the competition, and that the market would pay attention.
02What 'Astra' signals about the model family
The "Astra" suffix carries more information than a casual reading suggests. Within OpenAI's recent naming, the variant label distinguishes the primary flagship tier from the smaller, faster, and cheaper versions that share the generation number. When the company names a new model this way, it is telling developers which tier to expect pricing and capability to be anchored to, and that the rest of the family, mini and specialized variants, will be derived from it in the months that follow.
A flagship launch also resets the ladder below it. The previous generation's top model typically drops in price and becomes the default for cost-sensitive applications, a dynamic that has made one-generation-old flagships the workhorse of production AI deployments. For a developer deciding whether to adopt GPT-6 Astra on day one, the practical comparison is rarely against the previous flagship's launch price; it is against what that previous flagship costs now, after its own price decline.
There is also a competitive reading. Naming a model explicitly as the flagship tier is a claim directed at rival labs as much as at customers: Google's Gemini line, Anthropic's Claude line, and others release on their own cadences, and a new OpenAI flagship is a bid to hold the attention of developers who might otherwise evaluate the alternatives. The naming discipline is part of that positioning.
03How frontier LLM releases are evaluated
A large language model is, at its core, a system trained on vast amounts of text to generate, summarize, translate, and analyze natural language, and it is the basis of the modern chatbot ecosystem. A frontier release is judged by how far it pushes measurable capability along that dimension. The public evaluation ritual has become standardized: benchmark scores on reasoning, coding, mathematics, and multimodal tasks, side-by-side comparisons against the previous generation and against rival models, and a growing set of third-party leaderboards that test models after launch on conditions the vendors do not control.
The honest way to read a launch is to separate three layers. The first is vendor-reported results, which are real measurements but taken under conditions the vendor chooses. The second is early independent testing, which arrives within days and has the advantage of unfamiliar questions but the disadvantage of small sample sizes. The third is sustained usage over months, which is where differences in reliability, instruction-following, and cost-per-task become visible. Most buying decisions should be made on the third layer, and most launch coverage is written about the first.
One trend worth naming is that the headline benchmark gap between successive flagships has been narrowing in relative terms while absolute capability keeps climbing. Each generation still improves, but the improvement is harder to demonstrate with a single number, which pushes vendors toward differentiated claims, longer context, better agents, faster reasoning modes, rather than raw test scores. An announcement like this one should be read as the start of that evaluation cycle rather than its conclusion.
04The scaling debate behind every new release
Every flagship announcement is downstream of a bet about scaling. The GPT series was built on the observation that model capability improves predictably with more data, more parameters, and more compute, a regularity demonstrated most famously in 2020 and contested ever since. The current debate is not about whether scaling works but about its economics: each increment of capability costs more to train than the last, and the industry has been testing where the returns stop justifying the spend.
The practical consequence is that frontier labs have diversified what they scale. Post-training refinement, reinforcement learning on reasoning tasks, and inference-time compute, spending more compute at query time rather than training time, all now contribute to flagship capability in ways the original scaling story did not anticipate. A GPT-6 class model is best understood as the product of several optimization layers, not just a bigger version of its predecessor.
For the market, the scaling debate translates into a pricing question. Training runs in the hundreds of millions of dollars must be recovered through inference revenue, which is why flagship pricing has become a live competitive variable rather than a fixed list. Watch what OpenAI charges for GPT-6 Astra relative to GPT-5: it is the clearest public statement of how the company views the cost curve it is actually experiencing.
05Compute, cost, and the chip angle
A flagship model is inseparable from the infrastructure that trains and serves it. OpenAI's compute commitments, including the Stargate data center program announced in partnership with major infrastructure backers, are the physical substrate that makes a release like this possible. Frontier-scale training requires clusters that did not exist five years ago, and inference at ChatGPT-scale traffic requires a permanent and growing fleet of accelerators.
The chip layer is where the economics bite. NVIDIA has been the dominant supplier of the GPUs that train and run these models, and its data center business has become one of the largest hardware revenue streams in the history of computing on the back of AI demand. For its part, OpenAI has been reported to be developing its own accelerator program alongside partners, a move that mirrors what Google did with its Tensor Processing Unit more than a decade ago. A flagship launch is therefore also a statement about compute supply: the model exists because the silicon pipeline exists.
The consequence for consumers is indirect but real. Every fraction of a cent of inference cost per query is a function of how efficiently the serving fleet runs, and custom silicon, bulk GPU purchasing, and data center buildouts are all levers on that number. When a lab announces a new flagship, the price of using it is the variable that determines whether the announcement matters to anyone beyond benchmark watchers.
06What the announcement means for developers and consumers
For developers, a new flagship is a scheduled event in the product calendar, and the response it demands is evaluation rather than migration. The questions are concrete: does the new model solve failure cases in production, does its pricing shift the cost envelope enough to unlock features that were previously uneconomical, and does it change the trade-off between frontier quality and smaller-model speed. Most teams will run the new model alongside the old one for weeks before committing, which is the correct instinct.
For consumers, the flagship arrives as an upgrade to the chat products they already use, often without a visible change. ChatGPT's fifth-most-visited-site scale means that incremental capability improvements reach hundreds of millions of people as a quiet betterness in answers, coding help, and document handling rather than as a marketed event. The flagship generation is where the consumer product's quality floor is set, even when consumers never learn the model's name.
The timing also matters to both audiences. A launch this early in September positions the model as the reference point for the fall cycle of developer conferences and product updates across the industry, when rivals typically present their newest work. Announcing first is a deliberate play for that frame.
07Limits of what an announcement can tell you
The final caveat is the one that belongs at the top of every launch story: an announcement is a marketing event, not a measurement. The video that carried this news to a wide audience, a short segment from Yahoo Finance observed at roughly eight hundred views, is itself an example of how announcement coverage works, fast, broad, and necessarily thin on technical detail. Nothing in that genre substitutes for the technical report and independent evaluations that follow.
What can be said with confidence is structural. The release continues a cadence that has moved from three-year gaps between flagships to roughly annual ones, and that acceleration is itself the industry's most important product decision, a bet that customers will keep paying for each increment. The Astra naming signals a full-capability tier with variants to follow. The competitive context, Google's and Anthropic's parallel lines, is unchanged and will respond in kind.
What remains genuinely unknown is whether this generation produces a capability step that a non-expert would notice in daily use, or whether the gains concentrate in the long tail of hard tasks that benchmarks measure and few users touch. History suggests the honest answer arrives in about three months, from the developers who migrated, the leaderboards that stabilized, and the pricing that settled. That is the pace at which a launch becomes a fact.
By N43 and Hermes for Sailor Bob News.


