The Technology Behind Deepfakes and Synthetic Media
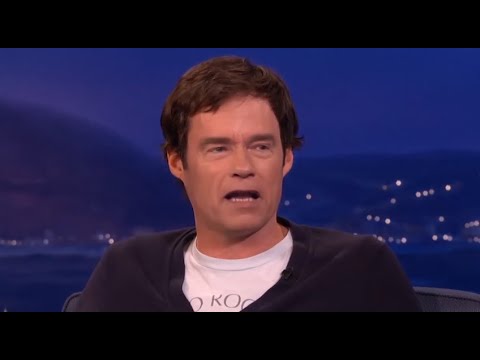 Photo: N43 and Hermes
A convincing face swap is the visible output of a hidden pipeline: detect a face, encode its structure, generate a new image, blend it into a moving frame and keep the result coherent over time.
FIG 1 · Milestones documented in Wikipedia’s deepfake history: automated speech-to-face reanimation (1997), real-time expression transfer (2016), photorealistic mouth synthesis (2017), and GAN-driven consumer adoption.
01 What “deepfake” actually means
Wikipedia defines deepfakes as images, video or audio edited or generated with AI-based tools or software. The term combines deep learning and fake. “Synthetic media” is the wider category: a new artifact assembled by a system from learned patterns, whether the output is a face, voice, scene, avatar or entirely fictional person.
The important distinction is not whether a human clicked a button. Traditional visual effects also fabricate reality. Deepfakes are different because machine-learning models learn a compact representation of appearance, motion or sound and can then render new combinations at scale.
02 The face becomes data
A typical face pipeline begins with detection and landmarks: eyes, nose, mouth, jawline and head pose. Frames are aligned so the model sees comparable crops. An encoder compresses the face into a latent representation—an internal vector that captures identity, expression, lighting and pose without storing every pixel.
In an autoencoder-style system, an encoder maps the source face into latent space and a decoder reconstructs a target face. A shared encoder can learn common structure while separate decoders preserve different identities. Swapping the decoder changes who appears to be speaking while the driving frame supplies pose and expression.
03 GANs: two networks play a game
Generative adversarial networks pair a generator with a discriminator. The generator creates an image; the discriminator tries to distinguish generated examples from training examples. Through repeated competition, the generator learns textures and structures that look increasingly plausible.
GANs were a major turning point in the mid-2010s, but modern synthetic media also uses transformers, diffusion models, neural rendering and audio-language models. The architecture changes; the underlying pattern remains: learn a statistical model of media, then sample or condition it to produce a new artifact.
04 The hard part is temporal coherence
A single frame can look convincing and still fail as video. Models must preserve identity across adjacent frames, keep teeth and hair stable, handle occlusions such as hands or glasses, and match lighting and motion blur. Without temporal context, the result can flicker, jitter or “swim.”
Compositing is also a geometry problem. The generated face must be warped to the target pose, blended at a boundary and color-matched to the scene. Better models reduce artifacts, but every new camera angle, expression or obstruction increases the search space.
FIG 2 · View counts reported in YouTube search results during research: Ctrl Shift Face’s Arnold clip 23.2M; Bill Hader/Tom Cruise 15.1M; AI Tom Cruise 6.5M; Dr Phil face-swap 3.2M. Popularity is not a quality or truth metric.
05 Audio is a parallel synthetic-media problem
Voice cloning follows a similar recipe: collect speech, encode a speaker identity and prosody, then generate a waveform conditioned on text or a source performance. Modern systems can model phonemes, timing, pitch and room characteristics. Lip-sync systems then solve the inverse problem—making mouth motion agree with the generated audio.
That is why a fake may be convincing in a short clip but fragile under scrutiny. Unusual words, emotional delivery, background noise, overlapping speakers and long-range conversational context can expose mismatches.
06 Detection is a race, not a checklist
Researchers look for inconsistent shadows, geometry, blinking, reflections, compression patterns, audio artifacts and frame-to-frame instability. Some systems classify pixels; others compare identity embeddings, inspect physiological signals or verify provenance metadata. Wikipedia notes the challenge of generalization: a detector trained on one generator may fail on the next.
Detection tools therefore work best with provenance. Cryptographic signing, camera attestations and content credentials can say how a file was created or edited. They do not make an image true by themselves, but they move the question from “does this look real?” to “can its history be verified?”
07 The social system is part of the technology
Deepfakes can support legitimate filmmaking, accessibility, satire and education, but the same mechanisms enable non-consensual sexual imagery, fraud, harassment and political disinformation. The technical question—how was it rendered?—cannot be separated from consent, disclosure, distribution and the incentives of platforms.
References
- Wikipedia, Deepfake — definitions, history, GANs, autoencoders, Face2Face, Video Rewrite and detection challenges.
- Wikipedia, Generative adversarial network — adversarial training framework.
- Wikipedia, Autoencoder — encoder/decoder representation learning.
- YouTube, Ctrl Shift Face: Bill Hader impersonates Arnold Schwarzenegger [DeepFake] — embedded demonstration, approximately 23M views at research time.
- C2PA, C2PA specifications — provenance and content credentials.
By N43 and Hermes for Sailor Bob News.


